Category: Cybersecurity

  • AI Code Security Requires a Strong Operating Model

    AI Code Security Requires a Strong Operating Model

    For small and midsized businesses, stolen source code is no longer just an intellectual-property problem. It can become an immediate security incident.

    An application repository shows attackers how a business handles logins, customer data, payments, administration, integrations, and internal workflows. They can search for weak authorization checks, exposed secrets, unsafe input handling, and obscure functions that have not been reviewed recently. Generative AI makes that work faster. An attacker no longer needs to inspect thousands of files manually before developing credible exploit hypotheses.

    That does not mean every SMB needs an advanced AI security research program. It does mean code security needs to be more systematic, particularly for businesses that operate customer-facing software, maintain proprietary applications, customize open-source platforms, or rely heavily on outside development firms.

    The useful lesson from emerging agentic code-review systems is not simply that AI can find vulnerabilities. AI is most useful when it operates with context, validation, and accountable human judgment.

    Why ordinary scanning is not enough

    Most organizations already use some combination of antivirus, vulnerability scanning, cloud security tools, and developer checks. Those controls remain important, but they do not always answer the question that matters most: Can an untrusted user reach a sensitive function and make it do something harmful?

    Conventional code scanners are often good at recognizing known risky patterns. They may flag an incorrectly constructed database query, an outdated library, or a hard-coded credential. But many application weaknesses depend on context spread across multiple files: a route that accepts user input, an authorization decision elsewhere in the application, a data transformation several functions away, and a dangerous operation at the end of the chain.

    A component may appear to require administrative privileges but use the wrong identity check along one path. An application may clean user input in one context, then later pass that same input to a system command, database query, or file operation.

    Finding these flaws requires following both:

    • Control flow: Who can invoke a feature and under what conditions.
    • Data flow: Where user-controlled information travels and whether it reaches a dangerous operation.

    AI-assisted source-code review can help because it can examine large volumes of code, identify potential entry points, trace relationships across files, and generate candidate attack paths much faster than a purely manual review.

    But speed can create another problem: a flood of plausible-sounding findings that consumes scarce technical time.

    The value is disciplined AI, not autonomous AI

    The more credible AI code-review approaches do not ask one model to “find all vulnerabilities.” They divide the work into stages.

    First, the system develops a threat model: what the application does, which components are exposed, what types of users exist, where sensitive data moves, and which modules are actually in scope. That matters because code that is never deployed, test code, or administrator-only functionality should not be treated the same as an internet-facing customer portal.

    Specialized processes can then identify application entry points—web routes, APIs, file uploads, or internal message listeners—and locate user input. Other stages gather the surrounding code needed to understand permissions, sanitization, routing, and downstream dependencies. The system can produce hypotheses about missing authorization, privilege escalation, SQL injection, cross-site scripting, command injection, or path traversal.

    Those hypotheses still need to be challenged. A sound process uses independent validation steps, removes duplicates, assigns risk, and places a human expert at the decision point. The reviewer should confirm that an issue is genuinely reachable and exploitable, including whether other controls prevent the supposed attack.

    For SMB leaders, the practical principle is simple: AI findings are leads, not facts.

    Treating every alert as a confirmed vulnerability creates cost and disruption. Treating AI output as infallible can also lead to unnecessary emergency changes—or cause teams to lose confidence in the tool after too many false alarms.

    Context is a security investment

    AI review quality depends heavily on the information supplied to it. A tool that sees only raw source code has less ability to distinguish a theoretical concern from a real business risk.

    Organizations can improve the value of a code-review service or platform by maintaining a few basic records:

    • An inventory of customer-facing applications, APIs, and critical internal systems.
    • Current architecture diagrams or concise descriptions of how systems connect.
    • A software bill of materials or dependable record of key libraries and components.
    • Clear ownership for each application and its code repositories.
    • Documentation of privileged functions, sensitive data stores, and third-party integrations.

    These do not need to be elaborate enterprise artifacts. For a smaller business, a current application inventory and a few well-maintained diagrams may be enough. The goal is to help technical reviewers understand which code is exposed, what it can access, and what a successful compromise would affect.

    Without that context, a team can spend time fixing low-value issues while overlooking an exposed workflow that could enable account takeover, customer-data access, or operational disruption.

    A realistic path for smaller organizations

    Most SMBs should not try to build their own multi-agent security harness. The more realistic decision is how to add deeper code review to existing development and risk-management processes.

    Start with the applications where a source-code compromise or exploitable defect would cause the most harm: customer portals, e-commerce systems, payment-related functions, systems holding regulated data, and software that manages administrative access. Commission a focused review after major changes, before a high-stakes launch, following a suspected repository exposure, or when replacing a development vendor.

    For ongoing development, maintain baseline controls: dependency and secret scanning, code review, timely patching, multi-factor authentication for source-control accounts, and restricted repository access. These are the foundation. AI-assisted review is a deeper layer for complex, business-critical code, not a substitute for secure development practices.

    Ask prospective providers direct questions:

    • How do they validate findings?
    • Can they demonstrate exploitability rather than provide only scanner output?
    • How do they handle source code, credentials, and customer data?
    • What remediation guidance will they provide?
    • Will they help distinguish urgent issues from technical debt?

    As AI reduces the effort required to analyze stolen or exposed code, businesses need to reduce the time required to understand and repair their own weaknesses. Continuous basic controls, combined with targeted expert-led analysis of the systems that matter most, remain the strongest approach.
  • MFA Gaps Exposed by Password-Spraying Attacks

    MFA Gaps Exposed by Password-Spraying Attacks

    Many small and midsized businesses believe account-takeover risk is addressed once multi-factor authentication is enabled. That assumption is understandable—and increasingly dangerous.

    Huntress reported a 155-fold increase in password-spraying attacks during the first half of 2026, including a campaign that generated more than 81 million login attempts in two weeks. The attackers targeted Microsoft cloud environments through an authentication path associated with Azure CLI, Microsoft’s command-line management tool for Azure and Entra resources.

    The lesson is not that attackers can generate enormous volumes of login attempts. They always could. The real issue is that an organization may have MFA, Conditional Access policies, and other visible controls in place while still leaving an authentication route where a password alone is enough.

    For an SMB, that is as much a governance problem as a technical one. Partially deployed controls create a misleading sense of protection just as leaders are deciding where to direct limited IT and security resources.

    Why Password Spraying Still Works

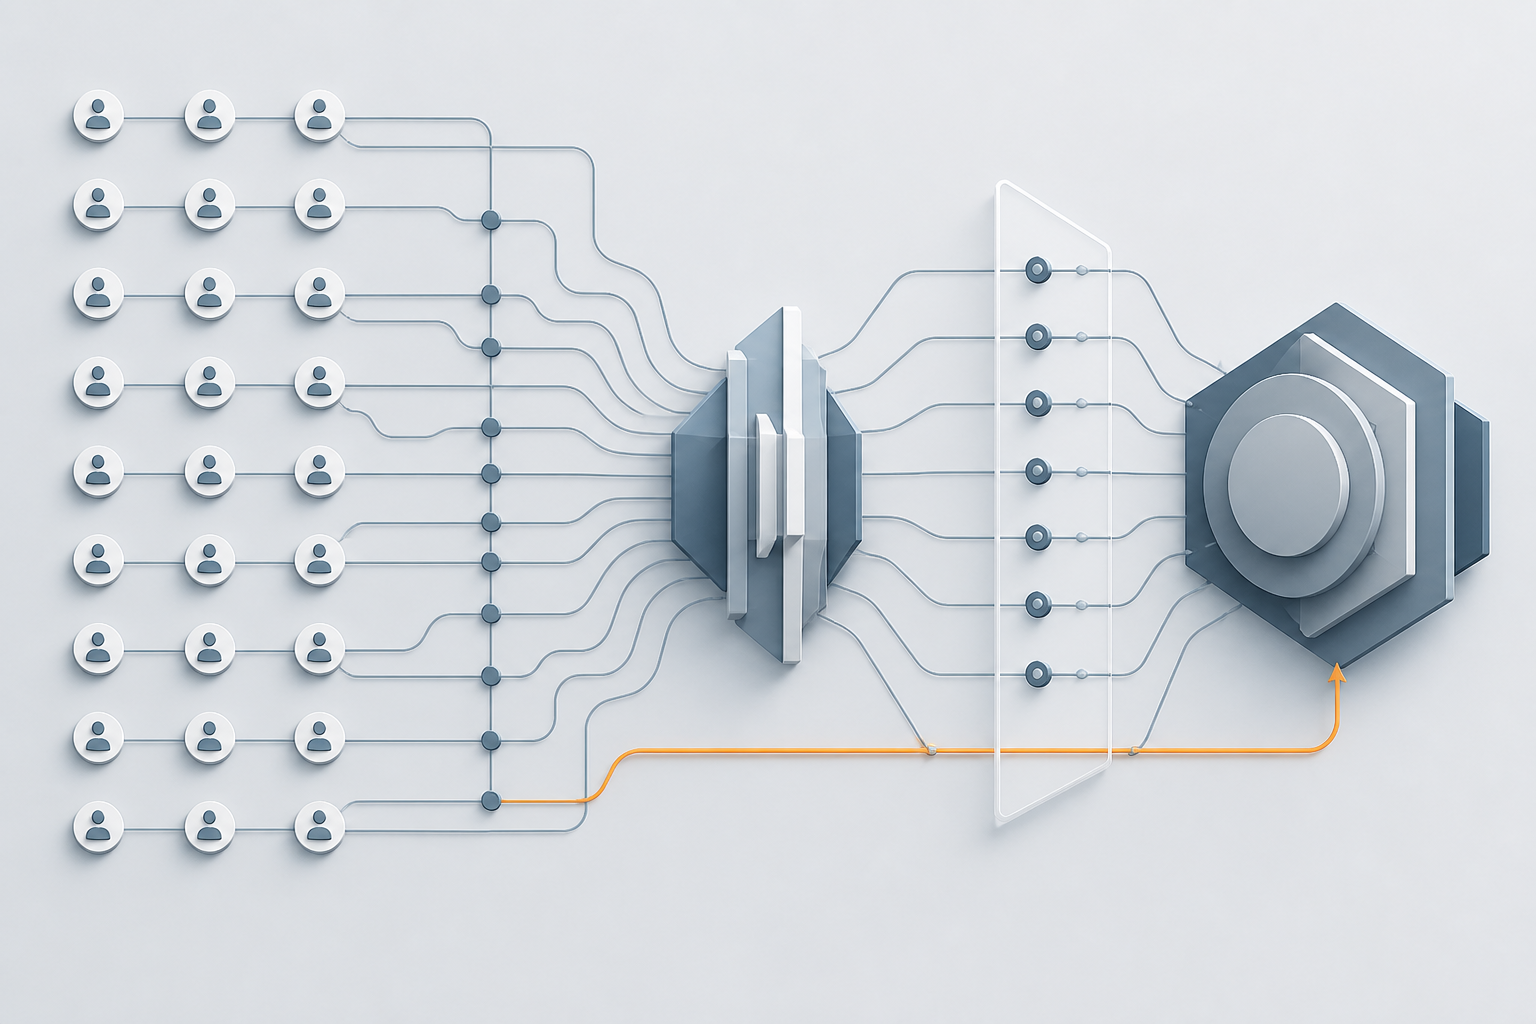
    Password spraying differs from the familiar brute-force attack that tries thousands of passwords against one account. Instead, an attacker takes a small number of likely passwords—or credentials exposed in an earlier breach—and tests them across a large list of employee accounts.

    The attacker moves slowly enough to avoid conventional account-lockout thresholds. Employee email addresses may come from public websites, LinkedIn, phishing campaigns, or prior data leaks. Attackers then test common passwords, company-related terms, or username-and-password combinations exposed in unrelated breaches.

    This works when employees reuse passwords or when old passwords remain active after a third-party breach. A successful login may lead to email fraud, payroll changes, invoice scams, customer-data theft, ransomware access, or further credential theft.

    In the campaign observed by Huntress, the attackers appear to have combined broad password spraying with known breached credentials. That makes each successful login more valuable. A working business account is not just access to one inbox. It may be a verified credential that can be sold, used for business email compromise, or leveraged to reach cloud data and administrative functions.

    Huntress did not observe follow-on activity after the compromises associated with this campaign. That does not make the event harmless. Credential validation has commercial value, and a quiet attacker may be building an inventory for later use or resale.

    The Problem Was Not Simply Missing MFA

    Of 23 affected organizations examined by Huntress, eight had no MFA at all. That is a straightforward exposure.

    The more revealing finding involved the other 15 organizations. They had MFA, but it did not apply to the sign-in method the attackers used.

    The attack abused Resource Owner Password Credentials, or ROPC, a legacy OAuth authentication method. Unlike modern interactive sign-in processes, ROPC sends a username and password directly to a token endpoint. It does not support the normal MFA prompt or single sign-on experience. If that pathway remains available and policy does not block it, a valid password can effectively bypass the protection leadership believes MFA provides.

    “MFA enabled” is not the same as “MFA required for every way an account can authenticate.”

    Conditional Access policies in Microsoft environments can be highly effective, but only when their scope and enforcement are complete. Policies may cover only certain applications, groups, or users. They may exempt trusted locations. They may remain in report-only mode during a transition and never be fully enforced. They may not cover older or noninteractive client authentication methods.

    Some exceptions are necessary during legitimate migrations. They also become durable attack paths unless someone is responsible for reviewing and removing them.

    Stop Treating This as an IP-Blocking Problem

    The campaign also shows why blocking suspicious IP addresses is necessary but insufficient. The observed activity moved through infrastructure providers and used bring-your-own-IP services, which allow customers to route traffic through address ranges they control. Attackers can switch providers and address ranges quickly.

    IPv6 makes the problem harder. Its vast address space gives attackers far more addresses from which to operate, reducing the practical value of blocking a limited set of source IPs. A defensive strategy built mainly around blocklists becomes an expensive game of whack-a-mole.

    The priority for SMBs should be making stolen or reused passwords less useful—not trying to identify every hostile machine before it connects. Authentication controls should assume that attackers will eventually obtain some valid employee passwords.

    What Leadership Should Do

    Ask the team responsible for Microsoft 365, Entra, or Azure administration a narrow question:

    Can any user authenticate with only a username and password through a legacy, noninteractive, or excluded sign-in flow?

    Request evidence, not a general confirmation that MFA is enabled.

    The review should include Conditional Access scope across all users, cloud applications, and relevant client application types. It should identify excluded users and applications, trusted-location exceptions, report-only policies, and legacy authentication methods. The objective is not necessarily to eliminate every exception immediately. It is to document each one, assign a business owner, and establish an expiration date or remediation plan.

    Disable ROPC and other legacy authentication methods unless there is a documented business dependency. If an application still relies on ROPC, treat it as a modernization risk with a specific replacement plan. A legacy integration should not quietly determine the security posture of the entire organization.

    Limit Azure CLI access to employees who genuinely need Azure administration capabilities. Most staff do not. Restricting administrative tools reduces the number of accounts and pathways that could be valuable to an attacker.

    Finally, improve password resilience. MFA remains the primary barrier, but unique passwords and a password manager reduce the chance that credentials exposed elsewhere will work in your environment. Where practical, move toward passwordless authentication or phishing-resistant MFA for administrators and high-risk users.

    Security controls should be measured by the access they actually prevent, not by whether they appear on a policy document. MFA is powerful when it is consistently enforced. When coverage has gaps, attackers need only find one route where the password is still the key.

  • GitHub Outages: Business Continuity Planning for SMBs

    GitHub Outages: Business Continuity Planning for SMBs

    A widespread GitHub outage is not automatically a cybersecurity incident. It may result from an internal service failure, a faulty change, a capacity problem, or an external dependency. For a small or midsized business, though, the immediate lesson is the same: a critical digital supplier can become unavailable without warning, disrupting far more than the development team.

    During the August 17 GitHub incident, the company reported elevated error rates across its website and API, along with problems involving Actions, webhooks, Issues, Pull Requests, and authentication services. Archive and raw repository downloads were especially affected. GitHub Copilot later showed degraded availability. Some services, including Git operations and Packages, remained available, but the outage still impaired functions businesses use to build, review, test, deploy, and support software.

    For organizations that depend on GitHub, this is a business continuity event. Can the company release changes, fix production issues, onboard staff, support customers, or respond to a security vulnerability while a core platform is impaired?

    The concentration risk behind a developer platform

    GitHub is often treated as a code repository. In many companies, it has become the software delivery system.

    Source code lives there. Pull Requests provide the required review and approval process. GitHub Actions runs automated testing and deployments. Webhooks trigger work in ticketing, monitoring, customer support, or release-management systems. Single sign-on connections govern employee access. Teams may also depend on raw files, archives, packages, hosted documentation, or cloud development environments.

    That integration is useful. It reduces friction and gives small technical teams capabilities that would otherwise require substantial internal infrastructure. It also creates concentration risk. A single provider outage can interrupt several business processes at once.

    The effect depends on the business. A software company may be unable to deploy a customer fix or release a promised feature. A manufacturer may be unable to update a customer portal or internal operational system. A professional-services firm that maintains custom applications may lose its normal process for supporting client systems. Even a company that does not sell software can be affected when its website, integrations, reports, or internal tools depend on GitHub-based automation.

    Authentication failures add another problem. GitHub reported issues involving SAML, OpenID Connect (OIDC), SCIM, and Team Sync. These services connect GitHub to a company’s identity provider and automate user access. When they are unavailable or unreliable, organizations face a difficult operational choice: delay access changes or create manual exceptions that may weaken normal controls.

    The answer is not to abandon centralized identity management. It is to plan for a dependency failure before an incident creates pressure to bypass safeguards.

    Availability is part of cyber resilience

    Cybersecurity discussions often focus on unauthorized access, ransomware, and data theft. Availability matters just as much. A service does not need to be breached to create material cyber risk for the business.

    A GitHub outage can interfere with security work itself. If a newly disclosed vulnerability requires an urgent application update, a degraded repository, CI/CD pipeline, or deployment approval process can slow remediation. If developers cannot access a dependency file, download a repository archive, or trigger a build, the organization may be stuck when speed matters most.

    Vendor security certifications and internal backups remain important controls. They do not answer the practical continuity question: what will the business do if a key cloud platform is partially unavailable for several hours?

    Partial outages are especially difficult. During the GitHub incident, some capabilities remained available while others experienced significant error rates. Teams may still be able to push code but be unable to load Pull Requests, reliably authenticate users, retrieve content, or run automated workflows. An up-or-down assumption leads to poor decisions. Response plans need to account for degraded service, not only total failure.

    Build a workable fallback

    Most SMBs do not need a fully synchronized secondary developer platform ready to replace GitHub immediately. Maintaining one can be expensive and operationally complex. They do need a practical fallback for the workflows that matter most.

    Start by identifying what would stop the business if GitHub were degraded for one business day. For many organizations, the list is short:

    • Access to the latest production source code
    • The ability to make and review an emergency change
    • The ability to deploy that change
    • A way to communicate release status internally

    Critical repositories should be regularly cloned or mirrored to a company-controlled environment with appropriately restricted access. A backup that requires the unavailable service is not a useful contingency.

    Preserve build instructions, infrastructure configuration, dependency information, deployment runbooks, and required secrets-management procedures alongside the code. Source code alone may not be enough to recreate a working release.

    Decide in advance how emergency changes will be approved if normal Pull Request workflows are unavailable. That does not mean abandoning review. It may mean a documented temporary process: two authorized reviewers, an emergency change record in another system, and a requirement to reconcile the change into the standard workflow when service is restored.

    Organizations that use GitHub Actions for deployments should determine whether a critical production fix can be deployed through a controlled alternative path. If no alternative exists, acknowledge that explicitly as an accepted business dependency and include it in incident planning.

    Establish clear communications as well. Developers should know who monitors vendor status, who decides whether work pauses, who can authorize emergency procedures, and how customer-facing teams will be informed when a release or fix is delayed.

    GitHub’s outage illustrates a broader reality. Cloud platforms can be secure, well managed, and temporarily unavailable. The goal is not independence from every supplier. It is preventing one supplier’s bad day from becoming your company’s operational crisis.

  • Lazarus Windows Zero-Day Campaign Lessons for SMB Leaders

    Lazarus Windows Zero-Day Campaign Lessons for SMB Leaders

    A serious cyberattack does not always begin with an obviously suspicious email, a crude fake website, or a technical failure inside the company.

    It can begin with a credible recruiter on LinkedIn.

    According to Check Point Research, the North Korea-linked Lazarus Group used fake job opportunities—some referencing recognizable companies including Lockheed Martin and Enveil—to lure professionals into opening documents or downloading a supposed PDF viewer. Attackers then deployed malware, exploited a Windows vulnerability to gain the highest level of control over an affected machine, and concealed activity from security tools.

    The reported campaign focused on defense and aerospace organizations in several countries. That should not lead other businesses to dismiss it. The methods involved—impersonated brands, search-result manipulation, trojanized software downloads, compromised websites, and unpatched Windows systems—apply to organizations of almost any size.

    The practical lesson for SMB leaders is simple: business trust is part of the attack surface.

    Recruiting conversations, vendor portals, software downloads, cloud services, and familiar websites can all be manipulated. The strongest defense is not expecting employees to identify every fake. It is building straightforward verification steps into normal business processes.

    This was a trust failure before it was a Windows vulnerability

    The reported campaign, known as Operation Dream Job, relied on social engineering before technical exploitation.

    Attackers reportedly posed as recruiters and asked targets to review a job description or install a PDF-reading application. In one infection path, victims downloaded an encrypted archive presented as a job-description document. In another, they were directed to a fraudulent PDF viewer called “SecurityPDF” through websites impersonating Enveil.

    Once installed, the malware could load a backdoor called Troy directly into memory. Check Point reported capabilities including file discovery, uploads and downloads, screenshots, remote command execution, process termination, and archiving data for exfiltration.

    The campaign also exploited a Windows privilege-escalation flaw in the Ancillary Function Driver for WinSock, or AFD.sys. Microsoft patched the flaw in its August 2026 Patch Tuesday updates, according to the source material.

    Privilege escalation matters because it turns a limited foothold into much greater control. In this case, attackers sought SYSTEM privileges—the highest access level on a Windows device. At that level, they can potentially interfere with security tools, establish persistence, access data available to the device, and operate with far fewer restrictions than a normal user account.

    Check Point reported that the attackers used elevated access to inject malicious code into a SYSTEM process and tamper with Windows Smart App Control, a feature intended to assess whether software is safe to run.

    For a business, the sequence is familiar and consequential:

    1. An employee takes an ordinary-looking action.
    2. Malware gains a foothold.
    3. An unpatched vulnerability gives the attacker more control.
    4. Security tools may no longer provide a clear view of the intrusion.
    5. A single endpoint becomes an operational, legal, and data-protection problem.

    That is why cybersecurity cannot be treated solely as an IT function. The initial decision often happens in a business workflow.

    SMBs may not be the target—but they can still be the route in

    Lazarus is widely associated with high-value espionage and financial objectives, and the reported targets were defense and aerospace organizations. Many SMBs do not hold military or aerospace intellectual property. They do hold customer records, payment data, contracts, pricing, product designs, employee information, credentials, and access to larger customers and suppliers.

    An SMB can also be valuable as a route to someone else.

    The source material describes attackers using compromised WordPress websites, SharePoint sites, and vulnerable Roundcube webmail servers as command-and-control infrastructure. In at least one case, a previously breached France-based organization was reportedly used to send phishing messages to new victims.

    That should concern any business leader. A company may not be the attacker’s ultimate objective and still suffer a costly breach because its email, website, domain, or trusted customer relationship is useful for reaching another organization.

    The consequences are practical:

    • Systems may need to be disconnected, investigated, and rebuilt.
    • Employees may lose access to email, documents, applications, or customer data.
    • Costs can include incident response, restoration, legal review, notification, lost productivity, and contractual penalties.
    • A compromised email account or website can damage customer and partner confidence.
    • Data exposure may trigger regulatory, contractual, or reporting obligations.
    • Larger customers may question a supplier’s security practices during renewal or procurement reviews.

    This is especially relevant for firms serving regulated industries, government agencies, financial services, healthcare, manufacturing, or technology. A preventable compromise can affect more than the immediate incident; it can affect the company’s ability to retain and win business.

    “Legitimate-looking” is no longer a useful security standard

    Traditional awareness training teaches employees to look for spelling errors, strange sender addresses, and suspicious links. Those checks still help, but they are no longer enough.

    Check Point reported that this campaign used several layers of apparent legitimacy: recruiter outreach through LinkedIn, recognizable names and branding, fake vendor sites, search results for terms such as “Enveil SecurityPDF,” compromised legitimate services, and phishing messages from an already compromised organization.

    A malicious download can therefore arrive through a plausible professional conversation, lead to a polished website, and communicate with infrastructure that does not immediately appear malicious.

    The problem is not employee carelessness. Attackers are exploiting normal professional behavior.

    The better model is not “teach people to spot every fake.” It is: do not require employees to make high-risk trust decisions alone.

    That means setting clear rules for:

    • Downloading software
    • Handling unexpected files and encrypted archives
    • Verifying vendor and recruiter requests
    • Responding to requests for credentials or multifactor authentication codes
    • Reporting suspicious messages without embarrassment or delay

    Recruiting deserves particular attention. People may engage privately with career opportunities, move quickly to avoid missing one, or hesitate to ask IT for help. The goal is not to regulate employees’ career choices. It is to prevent company devices and accounts from becoming the testing ground for unverified software.

    Employees should be able to discuss job opportunities privately, but they should not install software, enable macros, or open password-protected archives from an unsolicited recruiter on a company device. If a job description cannot be viewed with approved software, the employee should request a standard PDF or verify the recruiter through independently obtained contact information.

    A recruiter who asks someone to install software, provide credentials, share a multifactor authentication code, or access a company account should be treated as a potential fraud attempt.

    Patch management and software controls break the attack chain

    The campaign’s use of a Windows zero-day is a reminder that patching remains one of the highest-value risk-reduction measures available to an SMB.

    A zero-day is a vulnerability exploited before a fix is broadly available or before organizations have had time to apply it. No company can guarantee protection against every zero-day. But once a vendor releases a patch, delay becomes a controllable source of exposure.

    The reported AFD.sys flaw had a CVSS score of 7.0 and allowed local privilege escalation. That does not mean every unpatched Windows device would be compromised automatically. An attacker still needed an initial foothold, such as persuading a user to run malicious software. But the vulnerability could turn one successful social-engineering event into a much more serious incident.

    For resource-constrained businesses, effective patching does not require a large security operations center. It requires ownership and discipline:

    • Maintain an accurate inventory of managed computers, servers, network devices, business applications, and cloud services.
    • Enable automatic operating-system and application updates where feasible.
    • Define how urgent security updates are reviewed, tested, and deployed.
    • Track devices that miss updates because they are off-network, unsupported, or managed outside the organization.
    • Assign clear responsibility for reporting patch status and exceptions to management.

    Software acquisition is equally important. This attack depended on getting victims to install a trojanized PDF viewer. If employees can install software found through a web search, the company is relying on search rankings and individual judgment as primary security controls.

    That is not a sustainable model.

    Require business software to come from official vendor sites, managed app stores, or approved software-management tools—not search advertisements, third-party download sites, or unsolicited links. Maintain a short approved-software list and a simple exception process.

    Limit local administrator rights. Most employees should not be able to install software or make system-level changes without approval. IT staff should use separate accounts for routine work and privileged administration.

    Use application controls where feasible to prevent unknown or unapproved executables from running freely. The specific technology will vary, but the business objective is clear: stop an unverified program before it gains a foothold.

    Build a realistic 30-day improvement plan

    Endpoint security still matters. The reported Lazarus activity included a rootkit known as FudModule, updated to help conceal malicious tools and interfere with Windows protections. That is a reminder that endpoint protection is necessary, but it cannot be the only line of defense.

    Every managed endpoint should have centrally monitored security protection. It should be reinforced with multifactor authentication, reduced administrator access, protected and tested backups, restricted access to sensitive data, and a documented process for isolating a suspected compromised device.

    For many SMBs, the following actions provide meaningful risk reduction within 30 days.

    In the first week:

    1. Confirm that Windows and critical application security updates are being deployed. Ask for a concise report identifying fully patched systems, exceptions, and reasons for delay.

    2. Review who can install software. Remove unnecessary local administrator rights, beginning with sensitive systems and privileged users.

    3. Send a focused employee advisory on recruiter impersonation, encrypted archives, unusual PDF-reader requests, and software download links. Include a clear reporting contact.

    4. Verify endpoint-security coverage. Confirm that laptops, desktops, and servers have active protection and that alerts reach someone responsible for responding.

    Within 30 days:

    1. Create an approved-software list and an exception process for new applications.

    2. Review backups and test restoration of a representative file and a critical business system. A backup that has never been restored is an assumption, not a recovery capability.

    3. Require multifactor authentication for email, administrator accounts, VPN or remote access, cloud file storage, accounting platforms, and customer systems.

    4. Establish a basic incident-response checklist: who isolates a device, who contacts the IT provider, who assesses legal and notification obligations, and how employees report a suspected incident.

    5. Review internet-facing services—including websites, webmail, remote-access tools, and cloud applications—to ensure they are supported and patched. The reported use of vulnerable Roundcube servers shows why this cannot be ignored.

    6. Clarify third-party responsibilities. If an MSP, cloud provider, web developer, or vendor manages part of the environment, document who handles patching, monitoring, backups, incident notification, and emergency access.

    Leaders do not need to become malware analysts. They do need direct answers to a few operational questions: Which systems are unpatched? Can employees install arbitrary software? Who responds to endpoint alerts after hours? Can the company isolate a device quickly? Are backups tested? Who owns security obligations across third parties?

    “Everything is handled” is not an acceptable answer. Management should expect measurable information about coverage, exceptions, timelines, and ownership.

    The most useful discipline is also the simplest: when an unexpected request asks an employee to install software, open a protected archive, disclose credentials, or change a normal workflow, verify it through an independent channel before acting.

  • VMware vCenter Breach: A Business Continuity Threat

    VMware vCenter Breach: A Business Continuity Threat

    Many small and midsized businesses depend on VMware virtualization more than they realize. A single vCenter environment may manage file servers, accounting systems, customer applications, email-related services, remote-access tools, and backups.

    When that management layer is compromised, the problem is not confined to one server. It can affect the systems that keep the business running.

    Recent reporting from QUIRSO shows active exploitation of a critical Broadcom VMware vCenter vulnerability, CVE-2026-59310. The flaw has a CVSS score of 9.8 and could allow an attacker with network access to a vulnerable vCenter Server to execute arbitrary code.

    Broadcom issued patches late last month. Within days of public disclosure, investigators observed compromised systems contacting attacker-controlled infrastructure. QUIRSO identified as many as 361 victim IP addresses in 47 countries.

    For business leaders, the immediate issue is simple: a vulnerability in infrastructure-management software can become an operational, financial, and trust problem quickly. Patching is necessary. It is not enough to establish that an attacker did not gain access before the patch was applied.

    Why vCenter Deserves Executive Attention

    vCenter is a central platform for administering virtual machines and related infrastructure. In practical terms, it can be a control point for a large share of a company’s server environment.

    That makes it a high-value target.

    A compromised employee laptop may expose one user’s files, credentials, or access. A compromised virtualization-management system can provide a path to systems across the virtual environment. Depending on the design of the environment and the permissions available, an intruder may be able to observe, alter, disrupt, or extend access to business-critical systems.

    QUIRSO reported activity consistent with exploitation of a path- or directory-traversal flaw in vCenter, followed by installation of a malicious cron job and use of reverse_ssh, an open-source tool capable of creating an outbound SSH connection to attacker-controlled infrastructure.

    The important point is not the terminology. It is the sequence: an attacker gains access, establishes persistence, and creates a channel for continued remote access.

    A patch can close the original vulnerability. It does not automatically remove an attacker who already installed a scheduled task or remote-access mechanism.

    Patching prevents further exploitation of a known flaw. Incident response determines whether the flaw was already used to establish a foothold.

    Treating those as the same task creates a false sense of security.

    Persistent Access Changes the Risk

    The reported use of reverse_ssh matters because it changes the direction of the connection.

    Most organizations focus on blocking unauthorized inbound internet connections. A reverse SSH connection works differently: the compromised system initiates an outbound connection to attacker-controlled infrastructure. This can allow the attacker to interact with the system without opening an obvious inbound connection from the internet.

    reverse_ssh is not inherently malicious. It is open source and may have legitimate administrative uses. But when it appears unexpectedly on a vulnerable vCenter appliance—alongside unauthorized installation activity and unusual outbound communications—it is a high-priority indicator that requires investigation.

    This is particularly relevant for smaller organizations. They may not operate a 24-hour security function, have dedicated vulnerability-management staff, or maintain redundant infrastructure that makes emergency maintenance easy. Those constraints do not reduce the risk. They make rapid prioritization more important.

    QUIRSO reported that affected systems began contacting attacker domains on August 3, five days after Broadcom publicly disclosed the flaws. The company said this timing strongly suggests that public disclosure was the starting point for the campaign, while noting that the attacker may have had prior knowledge.

    The practical lesson is clear: when a critical flaw affects widely deployed infrastructure software, organizations should assume attackers will evaluate it quickly. A critical, actively exploited vCenter vulnerability belongs at the top of the patching queue.

    The Business Impact Extends Beyond vCenter

    A vCenter compromise can affect far more than the management appliance itself.

    If administrators must isolate systems, rebuild servers, restore backups, or investigate suspicious activity, downtime can spread across functions that otherwise appear unrelated. That may mean inaccessible business applications, disrupted file access and collaboration, delayed customer service or order processing, and emergency maintenance outside normal hours.

    The management challenge is equally significant. Leaders may need to decide which systems can be taken offline, which customer commitments are at risk, and whether backups and recovery systems can be trusted.

    The available reporting does not attribute this campaign to ransomware or identify a specific financial objective. Still, persistent access to a virtualization-management environment creates opportunities for disruption, data theft, misuse of systems, or later-stage attacks.

    For an SMB, the costs can include incident response and forensic work, emergency consulting, internal overtime, business interruption, recovery and rebuilding, contractual consequences, and—if sensitive data is affected—legal and notification costs.

    Customer and partner trust can also suffer. Customers do not distinguish between a virtualization-management appliance and the services it supports. They care whether the business can protect data and deliver reliably. Repeated outages, suspected unauthorized access, or poor communication during an incident can affect renewals and future sales conversations.

    A vCenter compromise does not automatically mean sensitive data was accessed or that notification obligations apply. Those questions depend on the systems affected, the data involved, and applicable laws and contracts. But a compromise can quickly require answers: Which virtual machines did vCenter manage? What data and applications were on them? Could an attacker have reached customer, employee, financial, health, or other regulated data? What contractual obligations may apply?

    That is why infrastructure incidents should be treated as potential governance issues early—not only after data loss is confirmed.

    Confirm Exposure, Patch, and Investigate

    Reporting also notes increased scanning activity associated with a separate critical VMware vCenter vulnerability, CVE-2026-59309. Defused Cyber observed fingerprinting and probing activity that may indicate attempts to identify systems vulnerable to that issue.

    QUIRSO stated that there was not enough evidence to link that scanning to the intrusion set or infrastructure associated with exploitation of CVE-2026-59310. Leaders should not assume that all activity involving critical VMware vulnerabilities is part of a single campaign.

    The response is still straightforward: organizations operating affected vCenter systems should promptly review both issues against Broadcom’s security guidance and apply relevant patches or mitigations.

    Leadership should expect clear answers to these questions:

    • Do we operate VMware vCenter directly or through a provider?
    • Which versions are deployed, and are they affected by CVE-2026-59310 or CVE-2026-59309?
    • Have the required vendor patches or mitigations been applied, and when?
    • Was vCenter reachable from the internet or broadly accessible within the network?
    • Have we looked for signs of prior compromise?
    • Are backups sufficiently separate from the systems and credentials used to administer virtualization?
    • Who owns the response if suspicious activity is found?

    The request is not for a lengthy technical report. It is for evidence that a system managing critical business services has an owner, a remediation plan, and a recovery path.

    Practical Steps That Reduce Risk

    First, identify every vCenter deployment—including branch offices, acquired businesses, disaster-recovery locations, and environments operated by third parties. For each instance, establish ownership, document the installed version, confirm whether it is supported, determine its exposure, and verify patch status.

    Next, use an expedited patch process. Review Broadcom’s advisory and instructions, confirm prerequisites and compatibility, schedule the earliest feasible maintenance window, take and validate backups where appropriate, and verify the update completed successfully. If the internal team lacks the expertise to perform the work safely, engage the MSP, VMware partner, or a qualified provider.

    At the same time, assess whether compromise may have occurred before patching. The reported activity warrants a review for unexpected cron jobs, unauthorized software or scripts, signs of reverse_ssh or other remote-access tools, unusual outbound connections, changes to administrative accounts, and abnormal authentication, configuration, or service activity.

    If suspicious evidence is found, preserve relevant logs and systems before making broad changes that could erase forensic evidence. Bring in incident-response expertise rather than relying only on ad hoc cleanup.

    Access to management systems should also be restricted. Where feasible, do not expose vCenter management interfaces directly to the public internet. Limit administrative access to designated management networks, VPN users, or approved jump hosts. Use individual accounts, role-based permissions, and multi-factor authentication where supported and practical. Review privileged access, especially for former employees, contractors, and vendors.

    Finally, review outbound connections from high-value management systems. The use of reverse SSH highlights a common weakness: organizations may tightly control inbound traffic while allowing broad outbound access from servers and appliances. Determine which outbound connections vCenter actually requires for updates, licensing, monitoring, support, and time synchronization. Block unnecessary access where feasible, and alert on unusual outbound traffic—particularly outbound SSH connections if they are not expected.

    Leadership’s Job Is to Demand Clarity

    Executives do not need to inspect cron jobs or firewall logs. Their role is to ensure that critical risks have owners, deadlines, evidence of completion, and a credible recovery plan.

    For this VMware issue, management should be able to answer four questions:

    1. Are we exposed?
    2. Have we patched the affected systems?
    3. Have we checked whether the vulnerability was exploited before patching?
    4. Can we continue operating and recover key services if this environment becomes unavailable or untrusted?

    If any answer is uncertain, assign that uncertainty to someone with the authority, expertise, and deadline to resolve it.

    For organizations using VMware vCenter, the priority is immediate: confirm exposure, apply the relevant fixes, and investigate for signs of persistence.